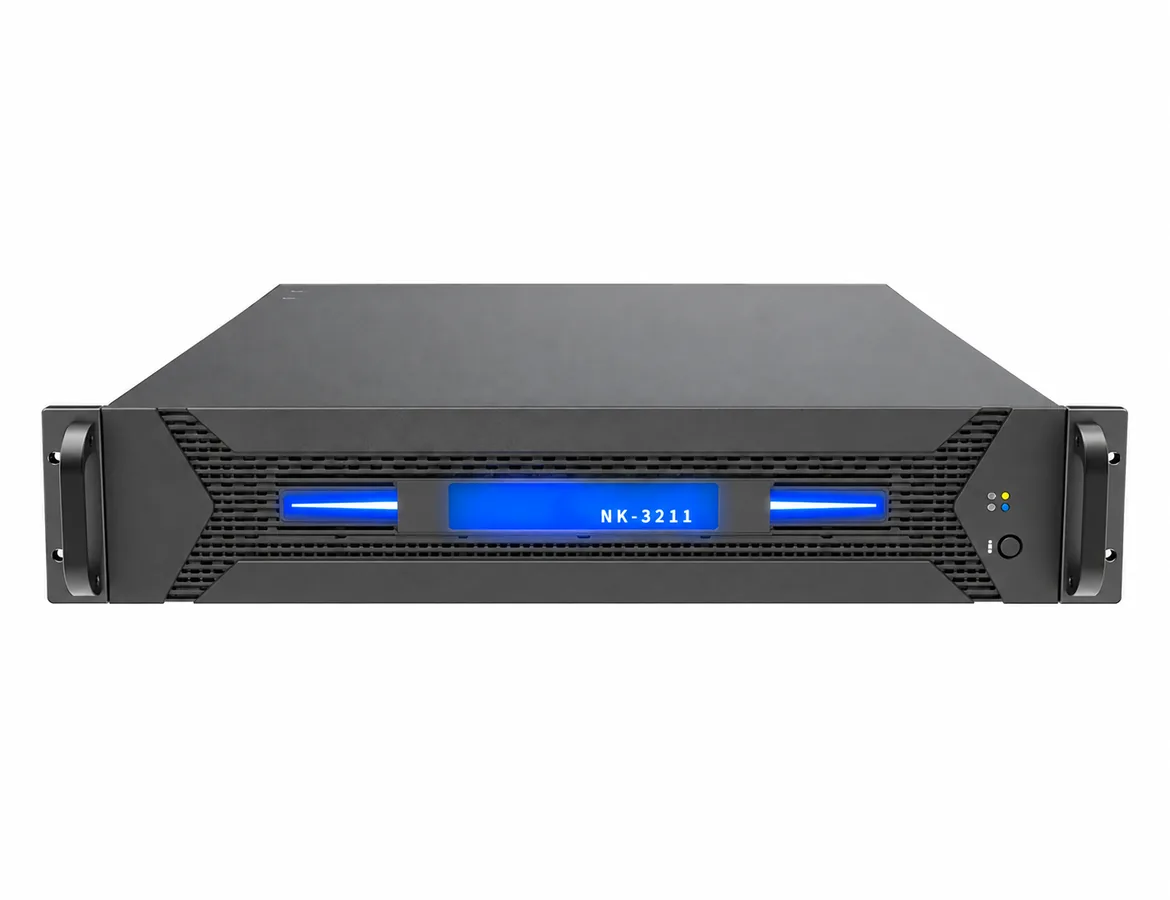
A Server That Comes Ready for AI Inference? TFNEW NK-3211
TL;DR: TFNEW launched the NK-3211, an inference-ready rack server, on September 21, 2026. Built around a domestic 920 ARM processor (24 cores at 2.6 GHz, 32-core option), it ships with a PCIe Gen 4 slot dedicated to an Atlas 300I accelerator, four 10GE/25GE optical ports and redundant 900 W power — a single-node AI server where the inference slot and the network are already planned for. Get specs and pricing: sales@tfnew.com.
Core Specifications (with Plain-Language Terms)
The NK-3211 is a rack server engineered around one idea: inference cards need a home. Five PCIe Gen 4 x16 slots are provided — one is dedicated to an Atlas 300I AI accelerator, so the card has guaranteed lane width and power headroom, and the other four stay free for NICs, storage controllers or additional accelerators. PCIe Gen 4 doubles the per-lane bandwidth of Gen 3, which matters when models and activations cross the bus every inference cycle. The system runs on a domestic 920 ARM processor with 24 cores at 2.6 GHz (24 threads), or an optional 32-core/32-thread variant, paired with up to 2x 3.5-inch and 2x 2.5-inch SATA/SAS drive bays and an optional hardware RAID card (RAID 0/1/5/10/50 or passthrough). Networking is generous for an inference node: four integrated 10GE/25GE optical ports plus two 1GbE, with a dedicated out-of-band management port. Power is redundant 900 W with 110–240 V input.
Specs at a Glance
| Item | NK-3211 Value |
|---|---|
| Processor | Domestic 920 ARM, 24 cores @ 2.6 GHz / 24 threads (32-core option) |
| AI slot | 1x PCIe Gen 4 x16 dedicated to Atlas 300I |
| Expansion | 5x PCIe Gen 4 x16 total (1 AI-dedicated + 4 standard) |
| Storage | Up to 2x 3.5" + 2x 2.5" SATA/SAS bays; optional RAID 0/1/5/10/50 |
| Networking | 4x 10GE/25GE optical + 2x 1GbE + dedicated management port |
| Power | Redundant 900 W, 110–240 V AC |
| Operating range | 10°C–35°C, 20–80% RH |
Why "Dedicated AI Slot" Is a Design Decision
Generic servers treat every PCIe slot the same, so an inference card often lands in a slot with the wrong width, wrong power budget or a NIC occupying its airflow lane. The NK-3211 allocates a dedicated x16 Gen 4 slot for the Atlas 300I — the card is a first-class citizen of the chassis, not an afterthought — while keeping four other x16 slots available. For teams rolling out model inference at the edge of a datacenter, that removes most of the integration guesswork: one SKU, one slot plan, one management story.
Where It Fits
- Model inference nodes: dedicated Atlas 300I slots for OCR, CV and NLP models in production
- Edge and regional sites: 25GE uplinks keep remote inference clusters synchronized with the core
- Secure/domestic deployments: domestic ARM processor for procurement lists that require homegrown silicon
- Virtualization with GPU headroom: four free x16 slots leave room for vGPU cards, high-speed NICs or NVMe controllers
Why the Numbers Matter
- 5x PCIe Gen 4 x16: one guaranteed slot for the Atlas 300I, four more for everything else
- 4x 10GE/25GE optical ports: inference traffic that doesn't bottleneck on the node uplink
- Redundant 900 W: a single PSU failure doesn't take the inference service down
- 24→32 core option: match CPU cores to model batch sizes without changing the chassis
What TF NEW Says
"Inference servers fail in boring places: wrong slot, starved power, uplink saturation," said a TF NEW product manager. "The NK-3211 removes the boring failures. The Atlas 300I gets its own x16 Gen 4 slot, the node gets 25GE uplinks and redundant power, and the whole thing runs on a domestic ARM processor — one SKU that a deployment team can plan around."
Quality and Availability
Every NK-3211 runs 48 hours of burn-in testing (sustained full load to flush out early failures) before shipping, with the Atlas 300I slot tested against a reference card in the factory. The system ships deployment-ready: BIOS defaults, management baseline and a documented slot plan.
Pricing and Availability
The NK-3211 is available now. Pricing varies with processor variant, RAID configuration and the Atlas 300I option. Contact sales@tfnew.com or use the request-a-quote form at www.tfnew.com/contact for volume pricing and lead time.
About TF NEW
TF NEW (TF New Technology) is an enterprise AI infrastructure provider based at www.tfnew.com. It designs and delivers private AI, compute, networking, storage, cooling and edge systems as deployment-ready solutions — AI servers, AI workstations, edge AI, liquid cooling and enterprise rack servers — for AI factories, datacenters and edge projects worldwide.
Media Contact
TF NEW | sales@tfnew.com | www.tfnew.com/contact
FAQ
- What makes the NK-3211 inference-ready? It ships with a PCIe Gen 4 x16 slot dedicated to an Atlas 300I accelerator, plus 25GE optical uplinks and redundant power.
- What processor does it use? A domestic 920 ARM processor — 24 cores at 2.6 GHz, with a 32-core option.
- How much expansion is available? Five PCIe Gen 4 x16 slots in total (one AI-dedicated, four standard).
- What storage does it support? Up to 2x 3.5-inch and 2x 2.5-inch SATA/SAS bays, with optional hardware RAID 0/1/5/10/50.
- Who is it for? Teams deploying Atlas 300I inference nodes with domestic-processor and high-bandwidth networking requirements.