Inference Plus Video in One Card? TFNEW Atlas300IDuo
TL;DR: TFNEW launched the Atlas300IDuo, a half-height AI inference card, on September 20, 2026. It pairs an Ascend 710 inference engine — 140 TOPS INT8 and 70 TFLOPS FP16 — with H.264/H.265 video encode/decode on the same card, so "look at the feed and decide" workloads run without a separate media server. 24 GB LPDDR4X and an on-card 8-core CPU keep preprocessing off the host. Get specs and pricing: sales@tfnew.com.
Core Specifications (with Plain-Language Terms)
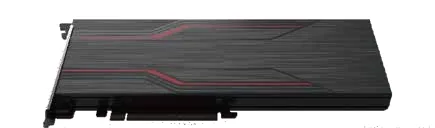
The "Duo" in Atlas300IDuo stands for two engines on one card: AI inference and video codec. The inference side uses the Ascend 710 chip at 140 TOPS (trillion operations per second in INT8, the format production AI models are quantized to) and 70 TFLOPS FP16 for mixed-precision work. The video side handles H.264/H.265 encode and decode plus JPEG — the codecs that surveillance cameras, webinars and media pipelines actually output. An 8-core 1.9 GHz CPU on the card preprocesses frames, and 24 GB LPDDR4X at 204.8 GB/s keeps models and streams resident. The card draws up to 72 W from a PCIe x16 Gen4 slot, so no extra power cabling is required.
Specs at a Glance
| Item | Atlas300IDuo Value |
|---|---|
| Form factor | Half-height, half-length PCIe card |
| AI chip | Ascend 710, secure boot, ≈2 TOPS/W |
| INT8 compute | 140 TOPS |
| FP16 compute | 70 TFLOPS |
| On-card CPU | 8 cores @ 1.9 GHz |
| Memory | 24 GB LPDDR4X, 204.8 GB/s |
| Codec | H.264/H.265 encode/decode; JPEG encode/decode |
| Interface / power | PCIe x16 Gen4, up to 72 W |
| Operating range | 0°C–55°C |
| Dimensions | 169.5 mm × 68.9 mm |
Why a DUO Card Beats Two Boxes
Most video-AI stacks run two pipelines: a media server that decodes streams, and an inference server that runs models. That is two machines, two power budgets and two failure points. The Atlas300IDuo collapses both pipelines onto one 72 W slot — decode happens in the codec engine, inference happens in the Ascend 710, and the on-card 8-core CPU stitches the two together. For OCR on invoices, ASR on call recordings, or moderation on live video, a single server can carry dozens of cards and scale jobs horizontally without adding media infrastructure.
Why the Numbers Matter
- 140 TOPS INT8 / 70 TFLOPS FP16: production-grade inference throughput for OCR, speech and ranking models
- H.264/H.265 + JPEG codec: handles the real-world formats of cameras and media pipelines, not just AI tensors
- 24 GB LPDDR4X at 204.8 GB/s: large models stay resident; stream data stays local
- ≈2 TOPS/W at 72 W: dense multi-card servers without power or cooling rework
- Secure boot: verified firmware for regulated deployments
Where the Atlas300IDuo Fits
- Smart surveillance: decode camera feeds and run person/vehicle detection on the same card
- Document AI: OCR and classification on scanned batches, with JPEG decode feeding the model
- Speech & contact centers: ASR on call recordings while the host keeps running other services
- Media monitoring: ingest, transcode and analyze broadcast or webinar streams in one pipeline
What TF NEW Says
"Most teams buy a decoder and then buy an inference card, and end up maintaining two fleets," said a TF NEW product manager. "The Atlas300IDuo is the answer to that: inference and video codec on one half-height card, 72 W, one slot. You deploy one fleet and scale it in one direction."
Pricing and Availability
The Atlas300IDuo is available now. Pricing varies with quantity and customization. Contact sales@tfnew.com or use the request-a-quote form at www.tfnew.com/contact for volume pricing and lead time.
About TF NEW
TF NEW (TF New Technology) is an enterprise AI infrastructure provider based at www.tfnew.com. It designs and delivers private AI, compute, networking, storage, cooling and edge systems as deployment-ready solutions — AI servers, AI workstations, edge AI, liquid cooling and enterprise rack servers — for AI factories, datacenters and edge projects worldwide.
Media Contact
TF NEW | sales@tfnew.com | www.tfnew.com/contact
FAQ
- What does the "Duo" in Atlas300IDuo mean? It pairs two engines on one card: Ascend 710 AI inference and H.264/H.265 video codec.
- Can it run inference and video processing at the same time? Yes — the codec engine handles encode/decode while the Ascend 710 runs inference, coordinated by the on-card CPU.
- How much compute does it deliver? 140 TOPS INT8 and 70 TFLOPS FP16.
- What memory and interface does it use? 24 GB LPDDR4X (204.8 GB/s) over PCIe x16 Gen4, up to 72 W.
- Where is it typically deployed? Surveillance, OCR/document AI, speech and media-monitoring pipelines that combine video with inference.